Synthetic Data Beyond the Hype: What the Research Really Tells Us About Its Future in Market Research
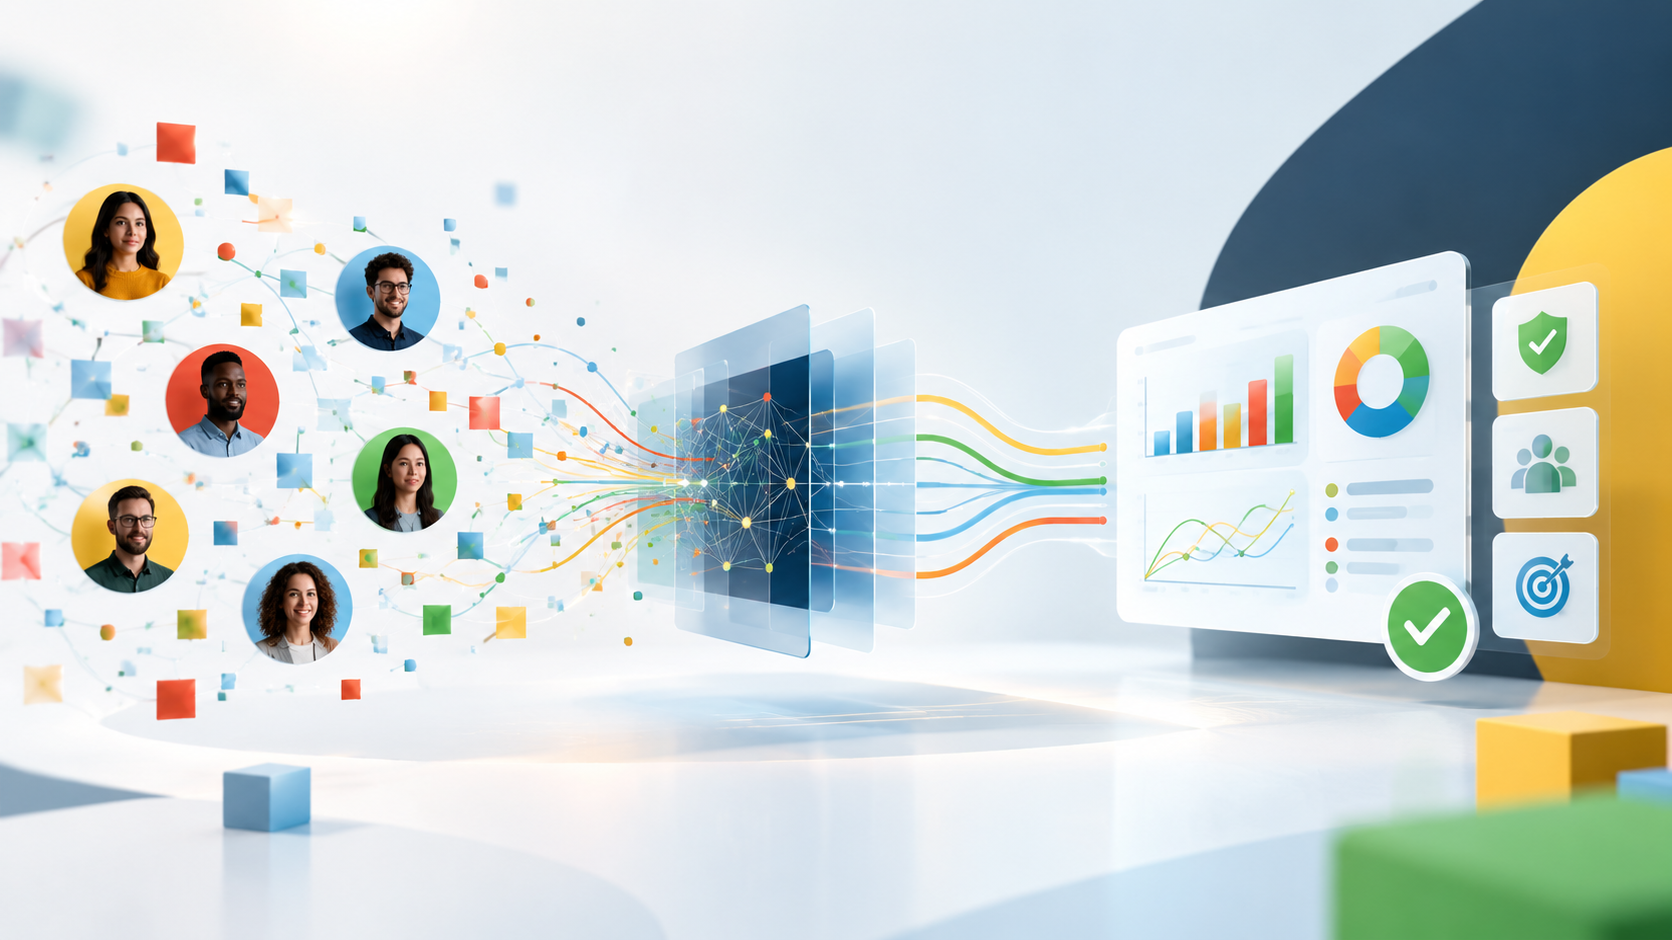
Synthetic data has become one of the most debated developments in market research. But the important question is no longer whether AI can generate human-like responses. It can. The more important question is: when do those responses provide reliable research evidence?
For organizations working in market research, the conversation around synthetic data is moving beyond AI-generated personas and impressive demonstrations. The industry is now asking harder questions about data quality, respondent validation, sample representation, research methodology and decision accuracy.
Major market research companies including Kantar, Ipsos and NIQ are exploring synthetic respondents and synthetic data applications. At the same time, academic researchers are developing frameworks to determine when synthetic respondents can be trusted, while recent experiments have demonstrated that AI-generated survey responses can fail to reproduce real-world opinions across certain questions and demographic groups.
For MR Buddies, this shift is particularly relevant.
The future of market research software is not simply about generating more data. It is about connecting high-quality respondent data, research execution, fraud prevention, panel management, AI and analytics into a reliable research ecosystem.
So the real question isn’t:
Can AI replace respondents?
It is:
Where can synthetic data make research faster and more intelligent without compromising the quality of the insight?
That distinction could shape the next generation of market research platforms, market research tools and AI market research tools.
The Synthetic Data Debate Has Changed
Early discussions around synthetic data focused heavily on scale.
If an AI model can simulate thousands of consumers within seconds, why conduct a survey with 1,000 respondents?
It sounds compelling.
But research methodology is rarely that simple.
A larger synthetic sample does not automatically mean a more representative sample.
If an AI model misunderstands a particular demographic, cultural context, emotion or emerging consumer behaviour, generating another 100,000 synthetic respondents simply creates more observations based on the same underlying limitation.
This is why the conversation is shifting toward questions such as:
- Can synthetic respondents reproduce real consumer behaviour?
- Which types of survey questions can they answer reliably?
- Which demographics are represented poorly?
- Does aggregate accuracy translate into individual-level accuracy?
- Can synthetic data improve an existing real dataset?
- How should synthetic results be validated?
- When should researchers avoid synthetic data altogether?
For companies building AI for market research, these questions are becoming more important than simply demonstrating that an AI model can generate realistic answers.
What Does the Research Actually Tell Us?
The evidence so far is mixed.
And that is exactly why synthetic data deserves a research-led discussion rather than a technology-led one.
Some studies indicate that synthetic respondents can reproduce certain patterns found in human research. Other experiments reveal substantial differences, particularly across demographic groups, emotional questions and topics where opinions are influenced by current events or lived experience.
This suggests that synthetic data is not one universal research methodology.
Its effectiveness depends on:
The data → The model → The population → The research question → The validation process
That framework is important for anyone evaluating best market research tools or considering AI-enabled research.
Synthetic Data Can Resemble Human Data — But Testing Matters
Kantar has conducted experiments comparing synthetic responses with responses from thousands of real survey participants.
Its research demonstrates that synthetic samples can show meaningful similarities to human data in certain situations.
But the conclusion is not that synthetic respondents can simply replace humans.
Instead, the research points toward a more careful approach: test synthetic data against real data for the specific research problem.
Kantar has explored potential applications including:
- Sample augmentation
- Data enrichment
- Predictive modelling
- Scenario simulation
- Difficult-to-reach audiences
- Research acceleration
However, the quality of the underlying real-world data remains critical.
This is an important lesson for market research companies.
Synthetic data does not remove the data-quality problem.
It can potentially amplify it.
If the original data is biased, outdated or poorly sampled, the synthetic model can reproduce those weaknesses at scale.
The Value May Be in Early-Stage Research
NIQ’s work on synthetic respondents provides another useful perspective.
Rather than positioning synthetic consumers as a universal replacement for conventional research, NIQ has explored their potential for innovation and concept evaluation.
Consider a typical innovation pipeline:
100 product concepts → 20 shortlisted concepts → 5 concepts tested with consumers → 1 product launch
The research challenge is determining which concepts deserve expensive human testing.
Synthetic respondents could potentially act as an early-stage screening layer.
That changes the question from:
“Can synthetic respondents replace our consumer research?”
to:
“Can synthetic respondents help us determine which concepts deserve real consumer research?”
That is a considerably more defensible application.
For market analysis, this distinction is critical because researchers can use AI to expand the number of scenarios they explore while reserving real respondents for decisions where authentic human evidence matters most.
Moving From Experimentation Toward Product Testing
Ipsos has taken synthetic-data experimentation into product testing and data augmentation.
The company has also explored digital-twin panels and validation in collaboration with Stanford researchers.
This development is important because it moves synthetic data closer to an operational market research platform rather than treating it solely as an AI experiment.
The methodology is particularly interesting because it focuses on comparing synthetic outputs with real-world characteristics.
Researchers can examine:
- Distributions
- Variances
- Means
- Relationships between variables
- Segment behaviour
- Individual-level patterns
The lesson for the industry is clear:
Synthetic data should be treated as a research instrument that requires validation.
It should not be treated as an unquestionable source of truth.
Academic Research: The Question Is “When,” Not “Whether”
Academic research is also making the synthetic-respondent debate more specific.
Recent research distinguishes between:
Generic AI respondents
The model is simply asked to behave like a particular consumer.
Segment-level synthetic personas
The model receives information about a defined consumer segment.
Individual-level digital twins
The model is grounded in information about an actual individual and attempts to estimate how that person might respond to additional questions.
These approaches are not equivalent.
A generic AI respondent may be useful for brainstorming.
A segment-level persona may be useful for scenario exploration.
An individual digital twin potentially has applications in data augmentation and estimating information that was not collected from an existing respondent.
For market research software, this distinction could become increasingly important as platforms begin integrating AI capabilities.
The “Forgotten Question” Use Case
One of the most interesting potential applications is what researchers might call the forgotten question problem.
Imagine that a survey contains 100 questions.
After fieldwork has finished, the client realizes that Question 101 should have been included.
Running the entire survey again may be expensive and time-consuming.
Could a validated digital-twin model estimate how existing respondents might have answered Question 101?
This is fundamentally different from asking an AI to invent 10,000 consumers.
The model already has information about real respondents.
The synthetic component is being used to augment an existing evidence base.
This could become one of the more interesting areas for AI market research tools because the AI is extending research rather than replacing the human foundation.
Pew’s 2026 Experiment: A Major Warning for Survey Research
[source : https://www.pewresearch.org/data-labs/2026/09/30/can-ai-stand-in-for-human-survey-takers-not-really/]
Recent research from Pew Research Center adds an important counterpoint.
In September 2026, Pew tested whether AI-generated synthetic respondents could reproduce findings from surveys conducted with members of its American Trends Panel.
The results showed significant limitations.
Synthetic respondents struggled to accurately reproduce public mood and produced particularly notable errors for certain demographic groups.
This is important because it demonstrates the difference between:
Generating an answer that sounds human
and
Generating an answer that accurately represents a population.
For market survey research, the second standard is what matters.
A synthetic response can be linguistically convincing while still being methodologically wrong.
Aggregate Accuracy Can Hide Individual-Level Failure
Suppose a real survey produces:
- 40% positive
- 35% neutral
- 25% negative
A synthetic sample produces almost exactly the same distribution.
At first glance, the synthetic sample looks accurate.
But there is another question:
Did the model identify which consumers would actually be positive, neutral or negative?
It may not have.
This distinction becomes critical for:
- Customer segmentation
- Personalization
- Audience targeting
- Product recommendations
- Brand strategy
- Individual-level prediction
For market research AI, aggregate accuracy is therefore only one measure of success.
Where Synthetic Data May Actually Work
Based on the current research direction, synthetic data appears particularly interesting for:
Concept Screening
AI-generated populations can potentially help researchers explore large numbers of early product or advertising concepts.
Questionnaire Pretesting
Synthetic respondents can help researchers identify confusing or repetitive questions before fieldwork.
Pilot Studies
Researchers can use synthetic populations to stress-test research designs.
Hypothesis Generation
AI can generate alternative explanations and possible consumer reactions that researchers can subsequently test with humans.
Data Augmentation
Synthetic observations may supplement real data where appropriate and after validation.
Scenario Modelling
Researchers can explore hypothetical market conditions before conducting expensive primary research.
Missing-Data Exploration
Validated individual-level models may potentially estimate variables that were not collected.
These are very different applications from simply saying:
“AI can replace our survey respondents.”
Where Researchers Should Be Cautious
Synthetic data becomes considerably more challenging when research depends heavily on real-world human experience.
Emotional Research
A model can generate language associated with an emotion.
That does not mean it has experienced the emotion.
Cultural Research
Subtle cultural, linguistic and regional differences can be difficult to reproduce accurately.
Emerging Categories
If there is limited historical data about a new category, there may be insufficient evidence from which to generate reliable synthetic behaviour.
Current Events
Consumer attitudes can change rapidly following political, social, economic or cultural events.
Minority Groups
If a population is underrepresented in the underlying data, synthetic modelling can potentially amplify the problem.
High-Risk Decisions
The more expensive the decision, the stronger the requirement for human validation.
This is why qualitative research companies and quantitative research organizations are unlikely to simply disappear because of synthetic data.
Human research remains critical when understanding why people think, feel or behave in a particular way.
The Biggest Risk: Synthetic Confirmation
There is another issue that deserves attention.
Suppose an AI model is trained on historical consumer data.
Researchers then ask:
“What will consumers think about our new product?”
The model generates an apparently reasonable answer.
But it may simply be reproducing historical patterns.
This creates a potential synthetic confirmation problem.
The model becomes very good at predicting what consumers used to think, while being less effective at identifying genuinely new behaviour.
This is particularly relevant for:
- New product categories
- Disruptive technologies
- New brands
- Cultural changes
- Emerging consumer trends
- Unprecedented events
For market analysis, this is a major consideration.
The past is useful for modelling the future—but it does not guarantee the future will behave like the past.
Data Quality Becomes Even More Important
Synthetic data does not eliminate respondent-quality problems.
It makes them more consequential.
Imagine that a research dataset contains:
- Bots
- Duplicate respondents
- Speeders
- Fake profiles
- VPN users
- Inconsistent responses
- Poorly profiled panel members
If that data is used as a foundation for AI modelling, those problems can potentially be reproduced by the model.
Therefore:
Before generating more data, research organizations need confidence in the data they already have.
This is where respondent-quality technology becomes part of the wider AI conversation.
Fraud-Cop: Protecting the Foundation of AI-Ready Research
For MR Buddies, this is one of the strongest connections between synthetic data and the broader research ecosystem.
Fraud-Cop is designed to help research teams identify suspicious online research behaviour, including issues such as bots, speeders, duplicate activity, VPN usage, suspicious IP patterns and copy-paste behaviour.
The relevance goes beyond traditional survey quality control.
If clean human data becomes the foundation for:
- AI modelling
- Synthetic respondents
- Data augmentation
- Predictive analytics
- Consumer segmentation
then protecting that original data becomes an AI-readiness requirement.
In other words:
Better synthetic research starts with better real research data.
MR CAWI ONLINE: Real Consumers Still Matter
The growth of synthetic data does not eliminate the need for primary research.
Online surveys remain one of the most important ways to capture genuine consumer opinions.
This is where MR CAWI ONLINE from MR Buddies fits into the broader research ecosystem.
A research team can use online research to:
- Recruit real respondents.
- Build the required sample.
- Set quotas.
- Collect genuine responses.
- Apply respondent-quality controls.
- Analyse the resulting dataset.
- Potentially use AI and synthetic methods as an additional layer.
The workflow therefore becomes:
Real respondents → Quality screening → Clean dataset → AI analysis → Synthetic augmentation where appropriate → Human validation
rather than:
AI → Synthetic respondents → Final business decision
For organizations serious about market research tools, that distinction is important.
MR CATI Tool: AI Does Not Eliminate Every Research Channel
The market research industry is becoming increasingly digital, but telephone research continues to have a role.
The MR CATI Tool from MR Buddies supports computer-assisted telephone interviewing and helps research teams manage CATI-based research workflows.
This is important because future research is likely to become increasingly multi-modal.
A single research program could combine:
- Online surveys
- CATI interviews
- Research panels
- Qualitative interviews
- Behavioural data
- AI analysis
- Synthetic modelling
The objective should not be to force every research question into AI.
It should be to select the right evidence source for the research decision.
MR PANEL APP: Why Real Respondents May Become More Valuable
There is an interesting paradox in the synthetic-data debate.
If AI can generate synthetic consumers, why would research panels become more important?
Because high-quality panels can provide the human benchmark against which synthetic models are evaluated.
The future could look like:
Real panel → Ground truth → Synthetic model → Simulation → Comparison with real panel → Validation
In this model, real respondents don’t disappear.
Their role evolves.
They become the benchmark for measuring whether synthetic intelligence actually reflects consumer behaviour.
This makes MR PANEL APP particularly relevant to the future of AI-enabled research.
A strong panel infrastructure can support:
- Respondent recruitment
- Profiling
- Segmentation
- Engagement
- Survey participation
- Longitudinal research
- Real-world validation
For MR Buddies, the panel therefore isn’t simply a respondent database.
It can be viewed as part of the research intelligence foundation.
MR SALES BOOSTER: Research Intelligence Starts Before Fieldwork
Synthetic data discussions often begin with respondents.
But a modern research project begins much earlier.
It starts with:
- Client requirements
- Research objectives
- RFQs
- Quotations
- Project planning
- Supplier management
- Sample requirements
- Fieldwork
- Reporting
MR SALES BOOSTER from MR Buddies addresses the commercial and pre-sales side of the research lifecycle.
This matters because the future of marketing automation systems and marketing automation software platforms is increasingly about connecting fragmented workflows.
AI-enabled research should not operate separately from the business processes that create research projects.
The opportunity is to connect:
Sales → Research design → Project management → Sampling → Data collection → Quality control → Analysis → Reporting
That is where integrated marketing project management software and research technology can create more value.
What This Means for the Future of Market Research Platforms
The rise of synthetic data could change what businesses expect from market research platforms.
A traditional workflow might look like:
Survey → Responses → Report
A next-generation research ecosystem could look like:
Research Design → Sales → Sampling → Panel → CAWI → CATI → Fraud Detection → Data Cleaning → AI Analysis → Synthetic Modelling → Validation → Reporting → Decision
This is where MR Buddies can position itself within the changing research landscape.
MR Buddies brings together technologies covering:
- Online research
- CATI
- Panel management
- Fraud prevention
- Sales management
- Project workflows
- Research operations
Its MR CAWI ONLINE, MR CATI Tool, MR PANEL APP, Fraud-Cop and MR SALES BOOSTER can therefore be positioned as components of a connected research ecosystem.
The underlying principle is simple:
AI can only be as useful as the research infrastructure supporting it.
A Better Framework for Evaluating Synthetic Research
Instead of asking:
“Is synthetic data accurate?”
research teams should ask several more specific questions.
1. Distributional Accuracy
Does the synthetic dataset reproduce important population distributions?
2. Relationship Accuracy
Does it preserve relationships between variables?
For example:
Does income relate to category purchasing in the same way as it does in the real dataset?
3. Segment Accuracy
Does the model work equally well across demographic and behavioural groups?
4. Individual Accuracy
Can the model meaningfully reproduce the responses of individual consumers?
5. Predictive Validity
Does synthetic output successfully predict something that later happens in the real market?
6. Stability
Do results remain consistent when prompts, models or generation conditions change?
7. Business Value
Does synthetic data actually improve the decision?
That final question is often missing from the discussion.
A technically impressive dataset has little value if it does not lead to a better business decision.
Synthetic Data Should Be Evaluated Against the Decision
Consider two different research problems.
Problem A: Packaging Innovation
A brand has 50 early packaging concepts and wants to identify which deserve further investigation.
Synthetic data could potentially provide an inexpensive screening layer.
Human research can then validate the strongest concepts.
Problem B: Patient Experience
A healthcare company wants to understand how patients experience a serious medical condition.
The requirement is fundamentally different.
The research depends heavily on lived experience, emotion and context.
Human research becomes much more important.
The technology is the same.
The research decision is different.
Therefore, the role of synthetic data should depend on:
Decision risk + research question + evidence quality + validation strength
What Should Research Organizations Do Now?
Organizations do not need to choose between synthetic data and traditional research.
A more practical strategy is controlled experimentation.
Start With Low-Risk Applications
Use synthetic data for exploratory work before applying it to high-stakes decisions.
Establish a Human Benchmark
Compare synthetic responses against actual respondent data.
Test Different Segments
Do not assume that a model performing well overall will perform equally well across every group.
Measure Differences
Evaluate statistical and behavioural differences rather than judging whether responses “sound human.”
Keep Real Respondents in the Research Loop
Human validation remains essential for important decisions.
Protect Your Underlying Data
Use strong panel management and fraud detection to ensure the real dataset is trustworthy.
Document the Methodology
Researchers should know how synthetic observations were generated and what assumptions the model makes.
The Future Is Probably Hybrid
The evidence does not suggest that the future of market research will be:
Humans vs. AI
It is more likely to be:
Humans + AI + real data + synthetic data + behavioural evidence
Synthetic data can potentially help researchers:
- Explore more concepts
- Test more scenarios
- Augment datasets
- Accelerate research
- Improve research design
- Identify hypotheses
- Reduce unnecessary fieldwork
But real respondents remain essential when the research question depends on actual experience, opinion and behaviour.
The competitive advantage may therefore belong to organizations that know when to use each type of evidence.
Where MR Buddies Fits Into This Future
For MR Buddies, synthetic data should not be positioned as a replacement for its existing research infrastructure.
Instead, it can be viewed as an emerging AI layer that can potentially sit on top of reliable research operations.
The foundation remains:
MR PANEL APP
Real respondents and panel intelligence.
MR CAWI ONLINE
Online quantitative research and consumer data collection.
MR CATI Tool
Telephone-based research and interviewing.
Fraud-Cop
Respondent-quality and fraud prevention.
MR SALES BOOSTER
Sales, client and pre-project research workflows.
Together, these capabilities support the research lifecycle from opportunity to data collection.
The future opportunity is to connect this foundation with increasingly sophisticated:
- AI analysis
- Predictive modelling
- Synthetic data
- Consumer simulation
- Research automation
- Decision intelligence
This creates a stronger proposition for organizations looking for best market research tools rather than isolated point solutions.
Beyond the Hype: What Researchers Should Really Ask
The most important question about synthetic data is not:
“Can AI generate a human-like answer?”
It clearly can.
The more important questions are:
“Does the answer represent the target population?”
“Can we validate it against real consumers?”
“Does it work consistently across segments?”
“Does it improve the research decision?”
And ultimately:
“Is it better than the alternative?”
These questions shift synthetic data from an AI novelty into a serious market research methodology.
Final Takeaway
Synthetic data is neither a miracle nor a failure.
It is an emerging research instrument.
The evidence from Kantar, Ipsos, NIQ, academic researchers and recent public-opinion experiments suggests that its value depends heavily on how it is generated, where it is applied and how rigorously it is validated.
For the market research industry, the strongest opportunity may not be replacing human respondents.
It may be using AI to make human research more focused, more scalable and more valuable.
That means:
Real respondents provide the evidence.
Research platforms provide the infrastructure.
Fraud prevention protects the data.
AI identifies patterns and possibilities.
Synthetic data can extend the evidence where appropriate.
Human validation keeps the research grounded in reality.
This is where MR Buddies fits into the evolving research landscape.
With MR CAWI ONLINE, MR CATI Tool, MR PANEL APP, Fraud-Cop and MR SALES BOOSTER, MR Buddies brings together key parts of the modern research workflow—from respondents and data collection to quality control and research operations.
The next generation of market research software is unlikely to be defined by one AI feature.
It will be defined by how effectively the entire research ecosystem works together.
For MR Buddies, that means a future where AI for market research is not positioned as a replacement for researchers or respondents, but as another layer of intelligence built on reliable research infrastructure.
Because the future of research isn’t simply about generating more data.
It is about generating better evidence—and turning that evidence into better decisions.
Frequently Asked Questions
What is the role of synthetic data in market research?
Synthetic data can potentially support concept screening, questionnaire testing, hypothesis generation, scenario modelling, data augmentation and other research activities. Its usefulness depends on the quality of the underlying data and validation against real respondents.
Can synthetic respondents replace real survey respondents?
Current evidence does not support treating synthetic respondents as a universal replacement for human respondents. Synthetic data is better viewed as an additional research instrument that can complement real consumer research.
Which market research companies are using synthetic data?
Organizations including Kantar, Ipsos and NIQ have publicly discussed or developed synthetic-data and synthetic-respondent applications.
Why is respondent quality important for synthetic data?
If synthetic models are built or validated using poor-quality real-world data, issues such as fraud, duplication or demographic imbalance can potentially be reproduced by the model. This makes respondent quality increasingly important.
What is Fraud-Cop?
Fraud-Cop is MR Buddies’ respondent-quality and fraud-prevention solution designed to help research teams identify suspicious online research activity and protect the integrity of research data.
How does MR CAWI ONLINE fit into AI-powered research?
MR CAWI ONLINE enables organizations to conduct online research with real respondents. This real-world data can provide an important foundation for analysis, validation and potentially AI-assisted research.
What is the role of MR PANEL APP?
MR PANEL APP supports panel engagement and respondent participation. High-quality real respondent panels can provide the human benchmark needed to evaluate synthetic research.
What does MR CATI Tool offer?
MR CATI Tool supports computer-assisted telephone interviewing, giving researchers another channel for collecting real consumer and respondent data.
How does MR SALES BOOSTER relate to market research?
MR SALES BOOSTER supports the commercial and pre-sales side of research operations, helping connect client requirements, opportunities and project workflows with the broader research ecosystem.
Is synthetic data the future of market research?
Synthetic data is likely to become one component of future market research platforms, but the evidence increasingly supports a hybrid model combining real respondents, primary research, AI, synthetic data and rigorous validation.